OpenViSTAI · Agents · Blockchain · Crypto
Menu
OPENVIST RECIPES

Validate CSV columns and detect duplicate rows with Python

Python

Check required CSV columns and identify exact duplicate rows before an import.

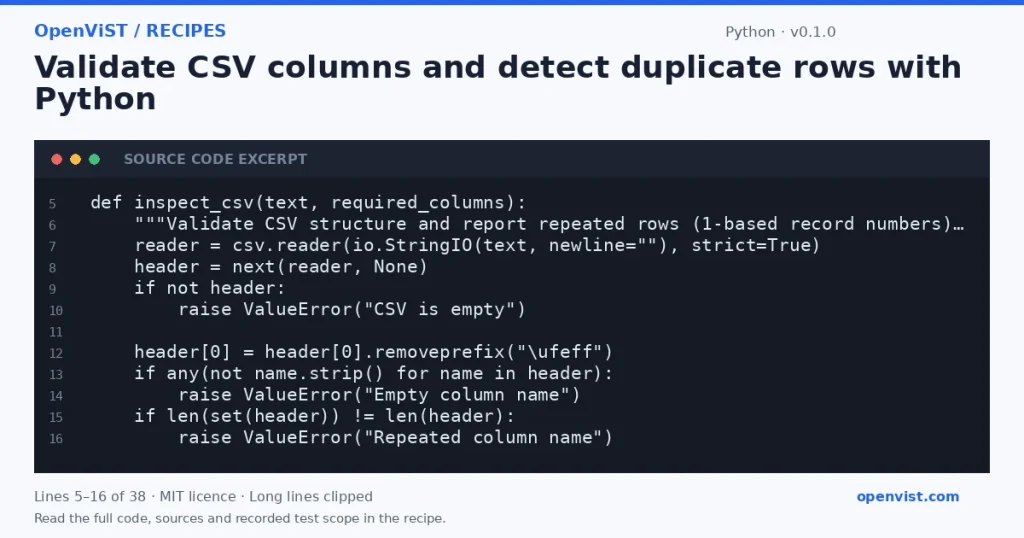
Python code excerpt: Validate CSV columns and detect duplicate rows with Python. Version 0.1.0. Read the full recipe for code, sources and recorded test scope.

Inspect modest comma-separated CSV inputs without changing them. This standard-library function checks the header and record width, then reports repeated rows against their first occurrence.

Before you start

  • Python 3.12; no external dependencies.
  • Decoded CSV text using comma separators.
  • Pass required column names as a list of strings.

Build and check

  1. Save the example code as recipe.py.
  2. Import inspect_csv and pass the CSV text and required column names.
  3. Inspect rows and duplicates in the returned dictionary.
  4. Handle ValueError and csv.Error before proceeding with an import.

Limits to understand

  • Compares complete rows exactly, including whitespace and letter case.
  • Does not validate data types or identifier uniqueness.
  • Accepts decoded text, not a file path; encoding is the caller's responsibility.
  • Record numbers count CSV records, not physical lines.
  • Memory grows with distinct rows; use modest inputs.
  • Header-only input is valid. Additional columns are allowed.

Run it

from recipe import inspect_csv
result = inspect_csv("id,name\n1,Jose\n1,Jose\n", ["id", "name"])
print(result)

Expected output

{'rows': 2, 'duplicates': [{'record': 3, 'first_record': 2}]}
INSPECT THE SCRIPT

Inspect, copy and run the documented checks.

This browser preview builds code locally. It does not contact an API or run the code.

Default example ready.

Python example
import csv
import io


def inspect_csv(text, required_columns):
    """Validate CSV structure and report repeated rows (1-based record numbers)."""
    reader = csv.reader(io.StringIO(text, newline=""), strict=True)
    header = next(reader, None)
    if not header:
        raise ValueError("CSV is empty")

    header[0] = header[0].removeprefix("\ufeff")
    if any(not name.strip() for name in header):
        raise ValueError("Empty column name")
    if len(set(header)) != len(header):
        raise ValueError("Repeated column name")

    missing = sorted(set(required_columns) - set(header))
    if missing:
        raise ValueError("Missing columns: " + ", ".join(missing))

    seen = {}
    duplicates = []
    count = 0
    for record_number, row in enumerate(reader, start=2):
        if len(row) != len(header):
            raise ValueError(f"Wrong column count in record {record_number}")
        count += 1
        key = tuple(row)
        if key in seen:
            duplicates.append({
                "record": record_number,
                "first_record": seen[key],
            })
        else:
            seen[key] = record_number

    return {"rows": count, "duplicates": duplicates}
What to verify after running
  • Seven test methods passed in the pinned Python Docker image.
  • Covered Unicode, BOM, duplicates, quoted commas and newlines.
  • Covered header-only input, invalid structure and unclosed quotes.

Request or format preview

Illustrative preview. No provider response, price or balance is fetched.

Change a setting to inspect the preview.

Official sources and related profiles

    Code license: MIT. Keep the license notice with your copy.

    Example version 0.1.0 · Documentation reviewed 2026-10-13.

    Seven unittest methods passed in an isolated Python 3.12 Docker container with networking disabled. Covers the listed fixtures; does not establish performance for large files or support for every CSV dialect.

    Related browser tools

    Inspect related data locally in your browser. These tools have their own input rules and limits; they do not execute this recipe.